
Updated 21 September 2026 · Model-specific comparison
This comparison covers Claude Fable 5.1 and DeepSeek-V4.1-Flash—not every Claude or DeepSeek product. The invitation-only Claude Mythos 5.1 is outside its scope. Check Anthropic’s model scope and DeepSeek’s current API model.
The practical difference is price and deployment, not a proven universal quality winner. DeepSeek lists much lower API prices and offers MIT-licensed weights. Claude Fable is available through Anthropic and major managed cloud platforms. API prices · DeepSeek model card · Claude availability.
Specifications and API costs
| Specification | Claude Fable 5.1 | DeepSeek V4.1 Flash |
|---|---|---|
| Context window | 1 million tokens | 1 million tokens |
| Maximum output | 128K tokens | 384K tokens |
| Input → output | Text and images → text | Text and images → text |
| Uncached input / 1M tokens | $10 | $0.15 off-peak / $0.30 peak |
| Output / 1M tokens | $50 | $0.60 off-peak / $1.20 peak |
| Cached input / 1M tokens | $0.25 | $0.003 off-peak / $0.006 peak |
These are token charges, not chat subscriptions. DeepSeek’s peak periods are 01:00–04:00 and 06:00–10:00 UTC on weekdays, excluding Chinese public holidays; all other hours are off-peak. Pricing rules.
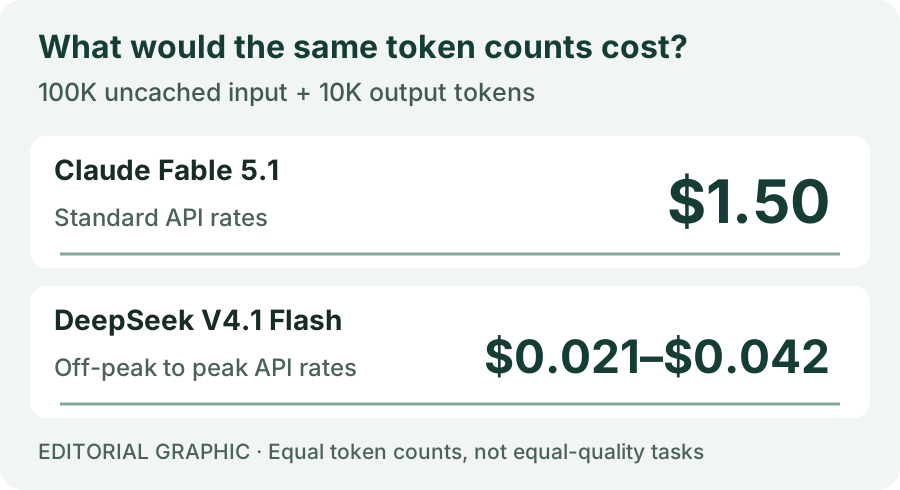
Illustrative calculation: 100,000 uncached input tokens plus 10,000 output tokens cost $1.50 with Fable, versus $0.021 off-peak or $0.042 at peak with DeepSeek. This excludes tools, cache writes, discounts, taxes and retries. Equal billed token counts do not guarantee equivalent work or quality. Claude rates · DeepSeek rates.
Pros and cons
Claude Fable 5.1
Pros: Managed access across several cloud platforms, a million-token context, and an offering positioned for demanding coding, research and document workflows. Cons: Substantially higher listed token prices; no downloadable self-hosting option is listed in its model documentation. Reasoning effort can change the bill, so measure completed tasks rather than judging the rate card alone. Specifications and positioning.
DeepSeek V4.1 Flash
Pros: Lower API rates, MIT-licensed weights, image understanding, and a larger listed maximum output. Cons: Open weights do not make deployment effortless: its 552-billion-parameter backbone implies substantial hosting infrastructure. Lower token prices do not establish lower total project costs once retries, integration and human corrections are included. Architecture and licence · API capabilities.
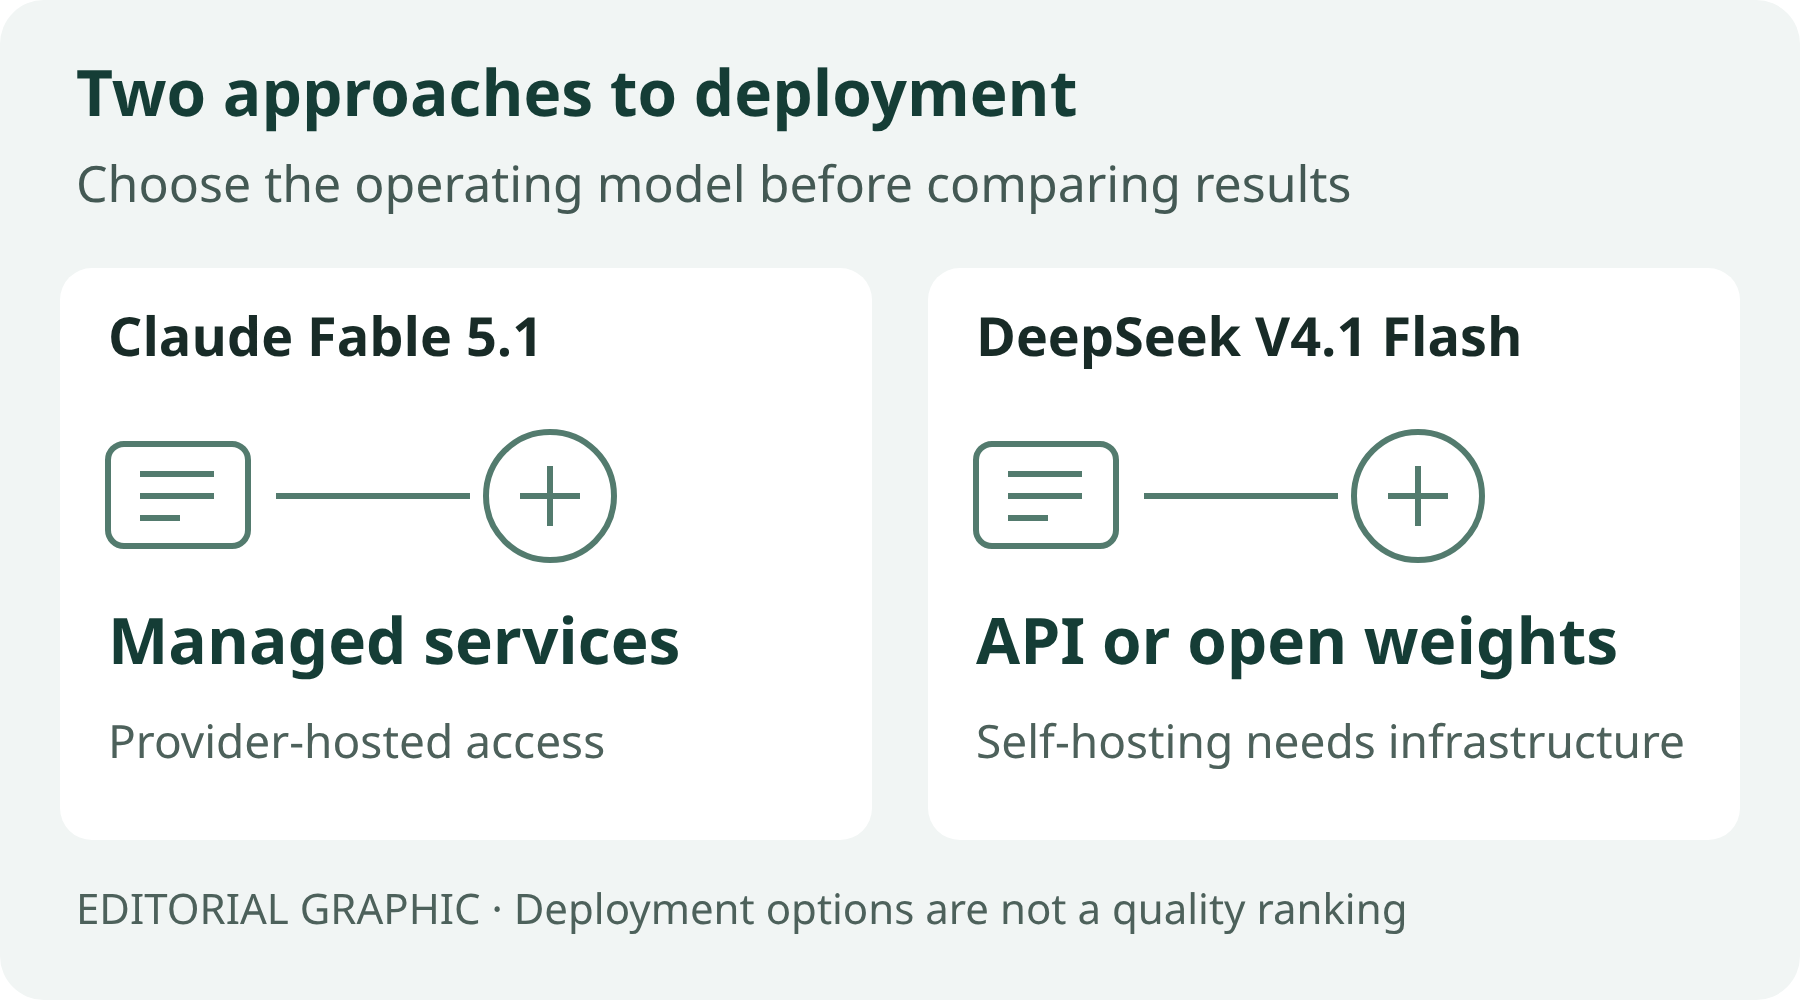
The two animated graphics above are editorial illustrations, not creations generated by either compared model. Their animation is decorative, not a performance measurement.
Real, publicly documented creations
These are attributed public examples, not fresh API runs performed for this article. Different prompts, effort settings and revision histories prevent a controlled head-to-head verdict.
Claude: an animated SVG pelican
Simon Willison published an SVG pelican riding a bicycle, then asked Fable 5.1 to animate a previous maximum-effort result using the High setting. The animation is therefore a second-stage creation, not a one-shot result. Read the prompt and revision history.
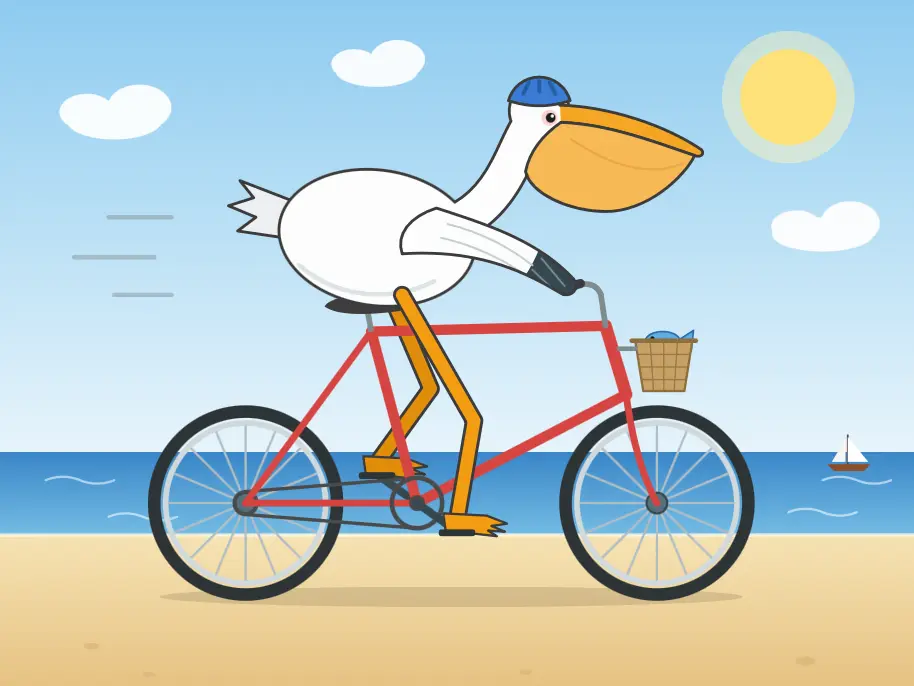
Open the live demo in a new tab.
DeepSeek: a browser game and SVG output
The VALOARENA creator attributes a browser game to DeepSeek V4.1 Flash through OpenCode. That is a developer’s report, not independently verified model provenance. The original account and public repository are available for inspection. Separately, BuseyBench records a V4.1 Flash SVG portrait with its prompt and downloadable output.
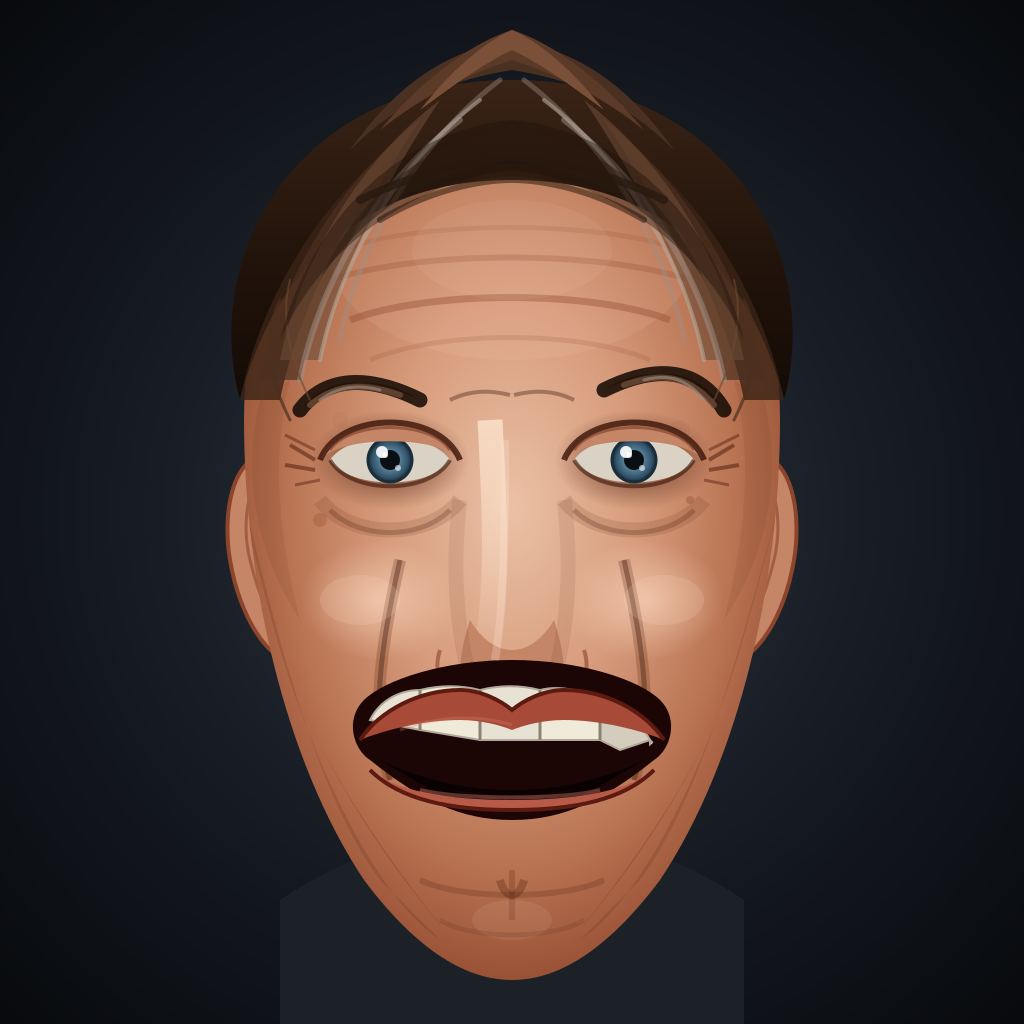
Open the live demo in a new tab.
The game uses desktop keyboard-and-mouse controls. External demo execution was not verified during preparation; source links remain available when an embed or remote preview fails.
Which should you choose?
Shortlist DeepSeek when API budget or downloadable weights are decisive. Evaluate Fable when its managed workflow fits your requirements. For the actual decision, give both the same task, grade correctness without model labels, and record billed tokens, retries and human fixes. Attractive demos are useful examples—not proof that either model is best overall.